
Using optical character recognition (OCR)
Kili Technology provides an interface for automatic transcription (or optical character recognition (OCR)) to extract text information from:
- an image document (for example, a scanned PDF document)
- a PDF document
Interface requirement
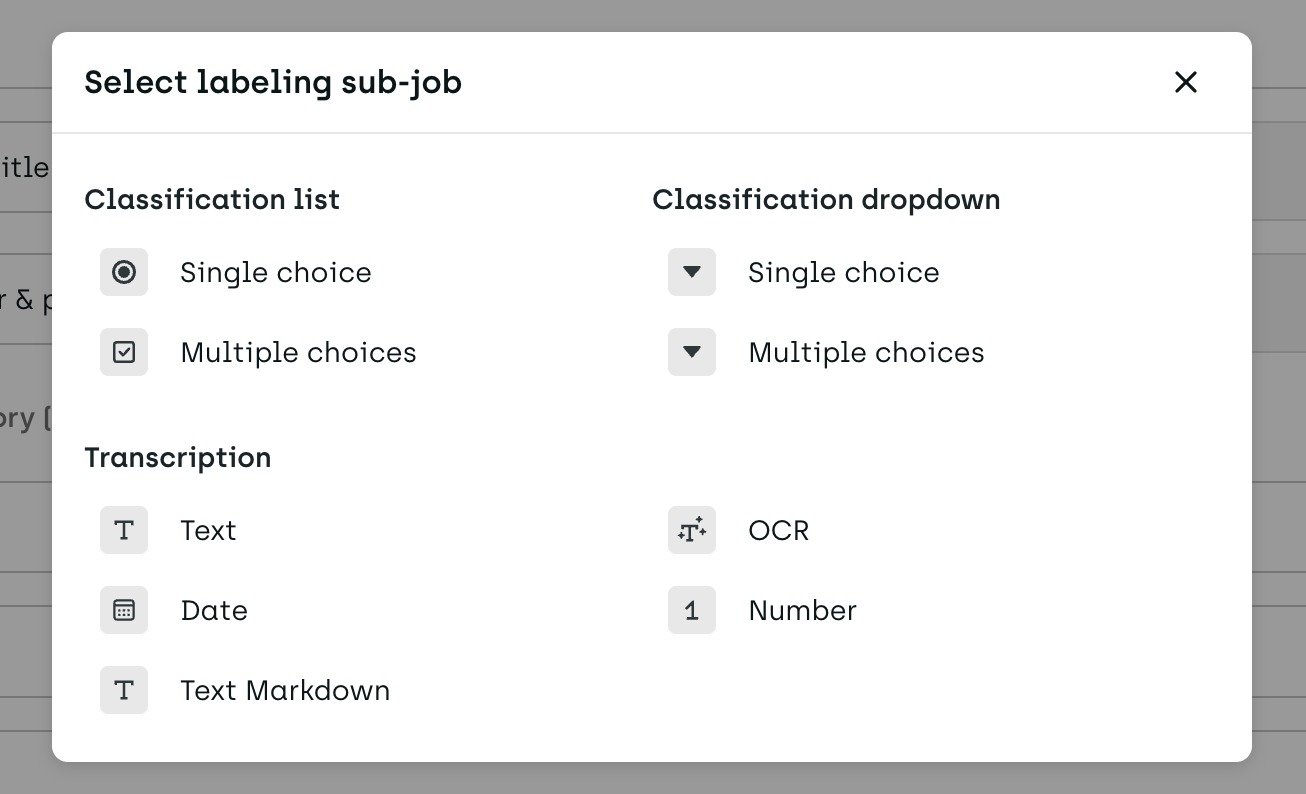
OCR transcription is available as a sub-job type in the labeling editor: under Transcription, select OCR. This sub-job type is only available on bounding boxes (BBoxes).
Note: This replaces the previous requirement of manually setting the autofill attribute.
How OCR works
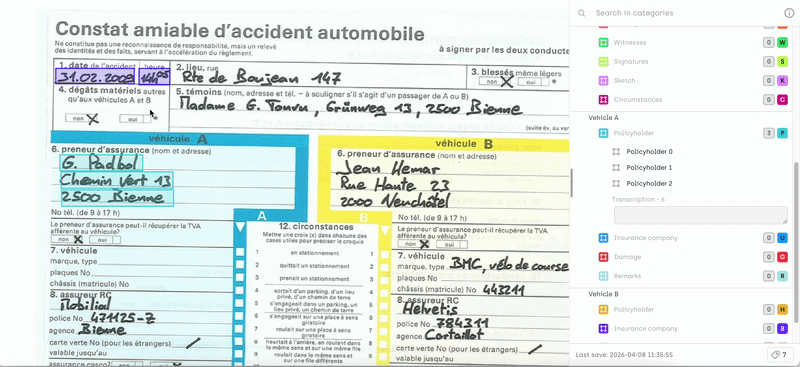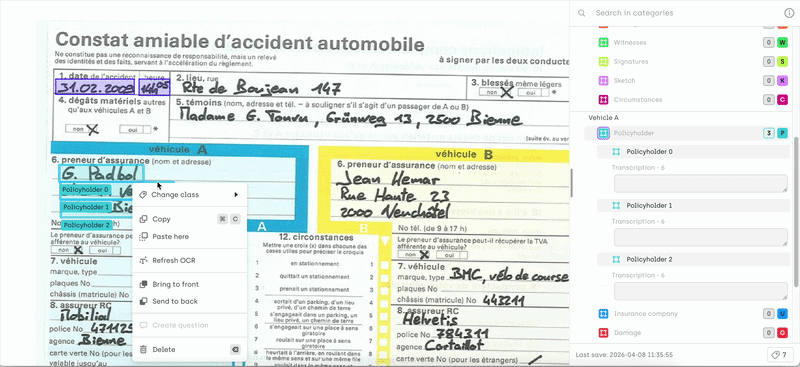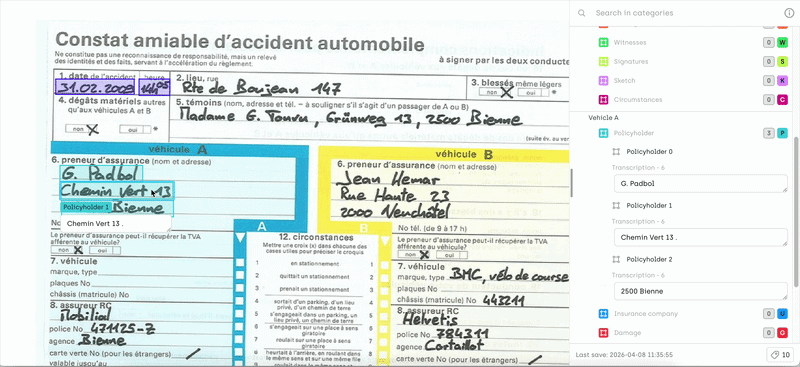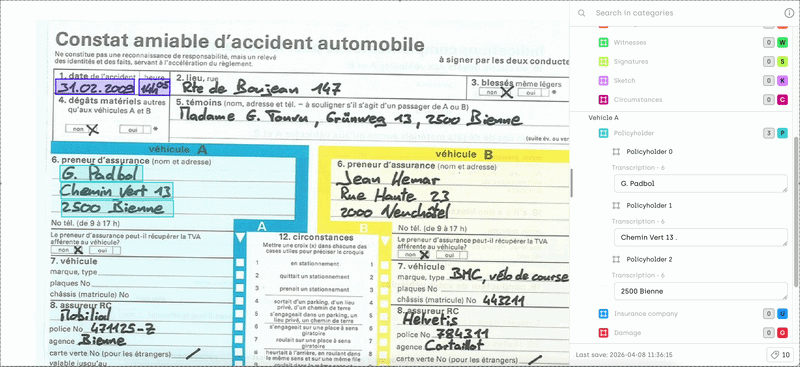
Kili natively extracts text from image and PDF assets, entirely client-side, in the annotator's browser. When a user draws a bounding box over a text area, the transcription is automatically populated based on the underlying content.
For PDF assets, native text is used directly when available; for scanned PDFs and image assets, text is extracted from the visual content.
Because OCR runs client-side, the document is never uploaded or transmitted to a server for processing. This guarantees that no text-bearing content leaves the local environment during OCR, which is essential for users working in on-premise deployments or under strict data residency and confidentiality requirements.
Setting the OCR language
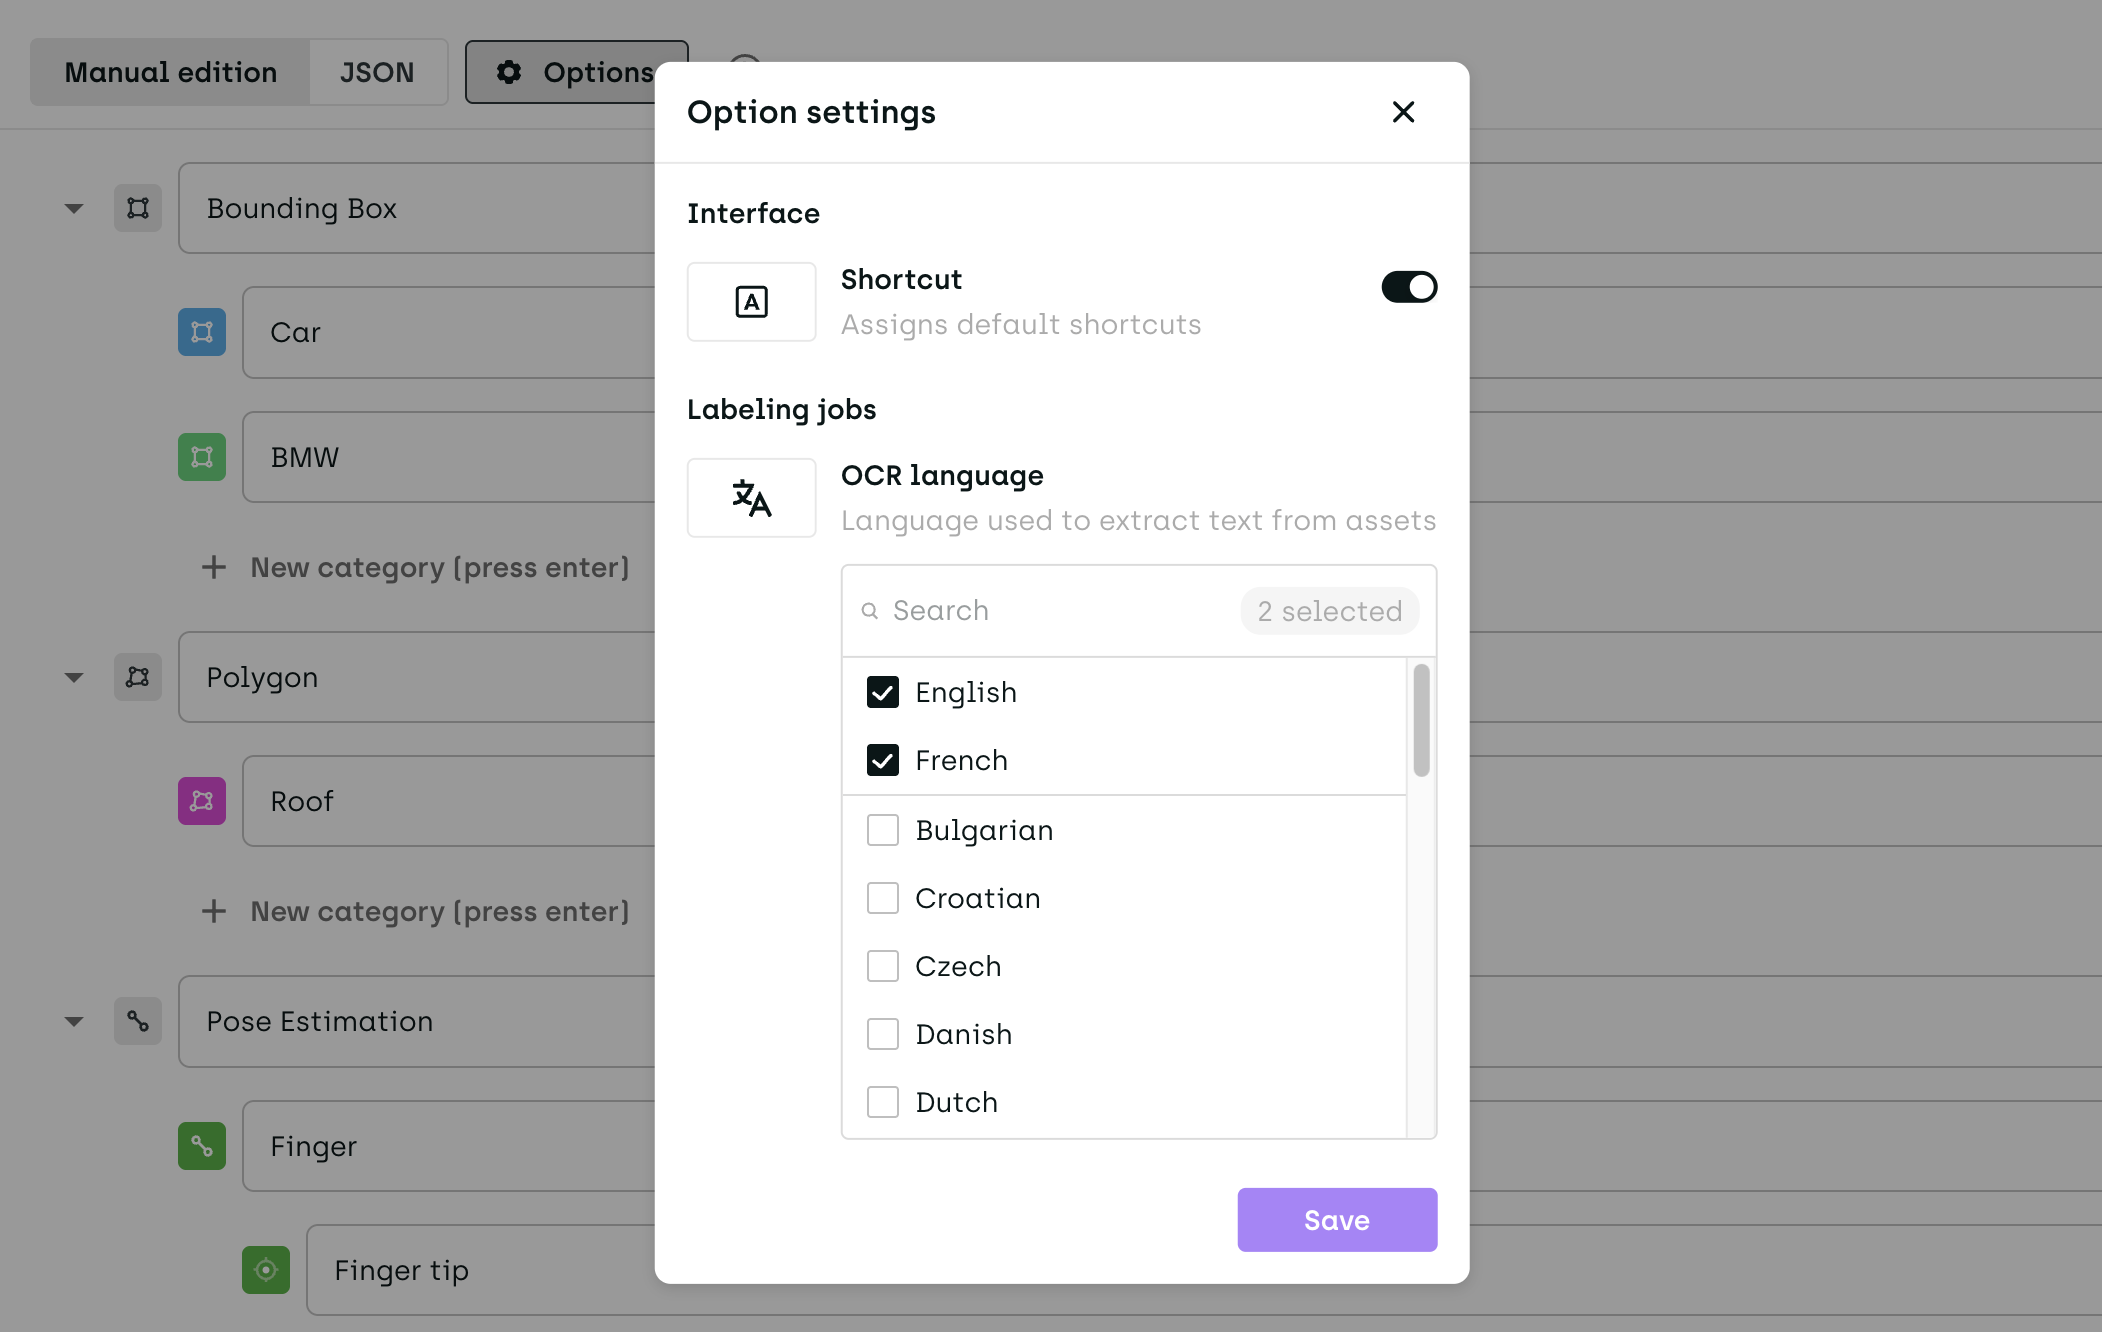
By default, text is extracted in English and French. To improve recognition on documents in other languages, you can select one or more OCR languages:
-
For the whole project: go to Labeling jobs and click Options. In the Option settings window, select the languages in OCR language, then click Save.
-
For the current asset: in the labeling interface, right-click an OCR annotation, choose OCR Language and select the languages. This change applies only to the asset you're working on; the project setting applies again when you move to another asset.
Changing the language doesn't update existing transcriptions: to apply it, refresh the OCR on the relevant bounding boxes.
The OCR language setting applies to Kili's native text extraction only. It has no effect on OCR metadata you import yourself.
Using your own OCR metadata
If native extraction does not meet your needs — for example, if you have higher-quality OCR results from a specialized model — you can import your own pre-computed OCR metadata instead.
To do so, include your OCR results in the jsonMetadata field when importing your assets. The expected format follows the structure produced by the Google Vision API. Each detected text element must be associated with coordinates in the image so Kili can match bounding boxes with the correct transcription.
For more details, see Importing asset metadata and this tutorial.
Creating OCR Annotations
OCR annotations allow you to extract and edit text from images using bounding boxes with transcription.
To create an OCR annotation:
- Select the bounding box tool configured with OCR transcription
- Draw a bounding box around the text you want to capture
- If autofill is enabled, the transcription will be automatically populated
- You can manually edit the transcription if needed
Refreshing OCR Transcriptions
When working with OCR annotations, you may need to adjust bounding boxes after their initial creation (e.g. moving or resizing them). In such cases, the existing transcription may no longer match the updated area.
You can refresh the OCR transcription to reflect the updated bounding box content.
How to refresh OCR
- Select one or multiple bounding boxes with OCR transcription
- Right-click on the selection
- Click "Refresh OCR"
The transcription will be recalculated based on the current position and size of each bounding box.
Updated about 19 hours ago